

西安电子科技大学学报 ›› 2025, Vol. 52 ›› Issue (5): 143-161.doi: 10.19665/j.issn1001-2400.20250801
陈素根1,2( ), 赵志忠1()
收稿日期:2024-09-23
出版日期:2025-10-20
发布日期:2025-08-19
作者简介:陈素根(1982—),男,教授,E-mail: chensugen@126.com;基金资助:
CHEN Sugen1,2(), ZHAO Zhizhong1()
Received:2024-09-23
Online:2025-10-20
Published:2025-08-19
摘要:
针对密度峰值聚类算法在变密度数据集上聚类效果不佳且样本分配过程会产生“多米诺骨牌”现象等问题,提出一种融合类簇生长及边界分配策略的密度峰值聚类算法。该算法利用局部k近邻信息计算样本密度和相对距离,进而得到样本决策值。基于样本间距离、密度和近邻关系定义样本间吸引度和生长半径,结合决策值依次选取类簇中心,提出类簇生长策略。该生长策略从每个类簇中心出发,利用吸引度和生长半径不断生长当前类簇以获得初始聚类结果。在此基础上,利用已分配类簇和未分配样本间近邻和距离信息定义邻接度,提出边界分配策略。该分配策略由邻接度将每个未分配样本划分到最合适的类簇中,不断更新已分配和未分配样本集,直到所有样本分配完成获得最终聚类结果。在16个人工数据集和10个UCI数据集上与7个算法的比较实验结果表明,所提算法在大部分数据集上的调整兰德系数、标准化互信息和调整互信息聚类指标均优于对比算法。同时,统计检验结果表明所提算法与对比算法在统计学上均有显著性差异,具有较好的聚类效果。
中图分类号:
陈素根, 赵志忠. 融合类簇生长及边界分配策略的密度峰值聚类[J]. 西安电子科技大学学报, 2025, 52(5): 143-161.
CHEN Sugen, ZHAO Zhizhong. Density peak clustering combining cluster growth and boundary assignment strategy[J]. Journal of Xidian University, 2025, 52(5): 143-161.

图1
以Jain数据集叙述DPC算法的问题"


图2
以Pathbased数据集叙述DPC算法的问题"


图3
CBDPC算法框架图"


图4
生长半径示意图"


图5
类簇生长及DPC算法在D3cno123数据集上的聚类结果"


图6
利用邻接度进行样本分配"


图7
边界分配策略在D3cno123数据集上所得最终结果"

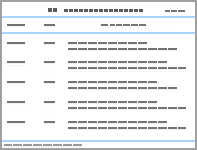
表1
人工数据集"
| 数据集 | 样本数 | 数据维度 | 类簇数 | 数据类型 | 数据集 | 样本数 | 数据维度 | 类簇数 | 数据类型 |
|---|---|---|---|---|---|---|---|---|---|
| 2d4c2 | 863 | 2 | 4 | 变密度 | Xclara | 3 000 | 2 | 3 | 类簇交叉 |
| Ls | 1 725 | 2 | 6 | 流形结构 | DS850 | 850 | 2 | 5 | 变密度、类簇交叉 |
| Donut2 | 1 000 | 2 | 2 | 流形结构 | D3cno123 | 715 | 2 | 3 | 变密度、类簇交叉 |
| Complex9 | 3 031 | 2 | 9 | 流形结构 | Compound | 399 | 2 | 6 | 变密度、类簇交叉 |
| DB | 629 | 2 | 4 | 流形结构 | Pathbased | 300 | 2 | 3 | 变密度、类簇交叉 |
| R15 | 600 | 2 | 15 | 类簇交叉 | Complex8 | 2 551 | 2 | 8 | 变密度、流形结构 |
| D13 | 588 | 2 | 13 | 流形结构 | Jain | 373 | 2 | 2 | 变密度、流形结构 |
| S1 | 5 000 | 2 | 15 | 类簇交叉 | Disk6000n | 6 000 | 2 | 2 | 流形结构 |
表2
UCI数据集"
| 数据集 | 样本数 | 数据维度 | 类簇数 | 应用领域 | 数据集 | 样本数 | 数据维度 | 类簇数 | 应用领域 |
|---|---|---|---|---|---|---|---|---|---|
| Libras | 360 | 90 | 15 | 运动识别 | DNA | 2 000 | 180 | 3 | 医学 |
| Wine | 178 | 13 | 3 | 农业物理学 | Heart | 303 | 13 | 2 | 医学 |
| Sonar | 208 | 60 | 2 | 物理学与化学 | Seeds | 210 | 7 | 3 | 农业 |
| Pima | 768 | 8 | 2 | 医学 | Thyroid | 215 | 5 | 3 | 医学 |
| Haberman | 306 | 3 | 2 | 医学 | Vote | 435 | 16 | 2 | 社会科学 |
表3
人工数据集上的聚类结果"
| 算法 | Jain | DS850 | |||||||
|---|---|---|---|---|---|---|---|---|---|
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 1.000 0 | 1.000 0 | 1.000 0 | 25 | 1.000 0 | 1.000 0 | 1.000 0 | 5 | |
| DPCSA | 0.233 0 | 0.042 2 | 0.216 7 | 1.000 0 | 1.000 0 | 1.000 0 | |||
| FHC-LDP | 1.000 0 | 1.000 0 | 1.000 0 | 18 | 0.995 4 | 0.996 6 | 0.995 3 | 43 | |
| ICKDP | 1.000 0 | 1.000 0 | 1.000 0 | 6 | 0.988 9 | 0.991 6 | 0.988 6 | 9 | |
| DBSCAN-DPC | 1.000 0 | 1.000 0 | 1.000 0 | 20/0.040 | 0.973 8 | 0.974 0 | 0.958 4 | 20/0.040 | |
| PPC | 0.645 6 | 0.705 5 | 0.610 3 | 3 | 0.991 7 | 0.993 3 | 0.991 7 | 17 | |
| DPC | 0.653 1 | 0.714 6 | 0.618 3 | 0.27 | 0.983 4 | 0.986 1 | 0.983 0 | 0.27 | |
| DPC-CE | 0.554 7 | 0.585 3 | 0.515 2 | 0.975 2 | 0.979 7 | 0.974 7 | |||
| 算法 | Xclara | D3cno123 | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 1.000 0 | 1.000 0 | 1.000 0 | 10 | 0.972 4 | 0.988 5 | 0.971 8 | 33 | |
| DPCSA | 0.992 0 | 0.995 9 | 0.992 0 | 0.721 5 | 0.668 8 | 0.677 8 | |||
| FHC-LDP | 0.995 6 | 0.998 0 | 0.995 6 | 9 | 0.910 3 | 0.939 1 | 0.892 0 | 19 | |
| ICKDP | 0.988 8 | 0.993 9 | 0.988 8 | 17 | 0.751 5 | 0.689 5 | 0.703 6 | 6 | |
| DBSCAN-DPC | 0.988 8 | 0.993 9 | 0.988 8 | 20/0.040 | 0.962 1 | 0.980 5 | 0.957 3 | 20/0.025 | |
| PPC | 0.997 6 | 0.999 0 | 0.999 7 | 16 | 0.946 8 | 0.969 9 | 0.938 7 | 3 | |
| DPC | 0.995 6 | 0.998 0 | 0.995 6 | 1.14 | 0.783 4 | 0.754 1 | 0.739 8 | 0.09 | |
| DPC-CE | 0.992 0 | 0.995 9 | 0.992 0 | 0.751 5 | 0.689 5 | 0.703 6 | |||
| 算法 | 2d4c2 | Ls | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 1.000 0 | 1.000 0 | 1.000 0 | 14 | 1.000 0 | 1.000 0 | 1.000 0 | 29 | |
| DPCSA | 0.993 0 | 0.995 9 | 0.992 8 | 0.759 7 | 0.628 2 | 0.744 9 | |||
| FHC-LDP | 0.993 0 | 0.995 9 | 0.992 8 | 14 | 1.000 0 | 1.000 0 | 1.000 0 | 45 | |
| ICKDP | 0.993 0 | 0.995 9 | 0.992 8 | 12 | 1.000 0 | 1.000 0 | 1.000 0 | 14 | |
| DBSCAN-DPC | 0.987 4 | 0.991 8 | 0.987 0 | 20/0.040 | 1.000 0 | 1.000 0 | 1.000 0 | 20/0.040 | |
| PPC | 1.000 0 | 1.000 0 | 1.000 0 | 33 | 0.785 7 | 0.646 3 | 0.748 6 | 6 | |
| DPC | 0.932 1 | 0.955 5 | 0.914 0 | 1.22 | 0.749 1 | 0.619 2 | 0.688 0 | 0.36 | |
| DPC-CE | 0.875 6 | 0.864 7 | 0.824 2 | 0.730 5 | 0.626 6 | 0.700 2 | |||
| 算法 | Donut2 | D13 | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 0.973 5 | 0.988 0 | 0.973 5 | 7 | 0.980 0 | 0.970 5 | 0.974 0 | 14 | |
| DPCSA | 0.966 4 | 0.984 0 | 0.966 3 | 0.852 5 | 0.577 9 | 0.801 0 | |||
| FHC-LDP | 0.966 4 | 0.984 0 | 0.966 3 | 40 | 0.972 3 | 0.941 3 | 0.967 3 | 6 | |
| ICKDP | 0.966 4 | 0.984 0 | 0.966 3 | 12 | 0.958 8 | 0.933 3 | 0.949 5 | 5 | |
| DBSCAN-DPC | 0.966 4 | 0.984 0 | 0.966 3 | 20/0.030 | 0.972 6 | 0.949 0 | 0.943 4 | 11/0.034 | |
| PPC | 0.225 4 | 0.122 0 | 0.185 6 | 50 | 0.918 2 | 0.805 2 | 0.806 1 | 19 | |
| DPC | 0.266 2 | 0.177 5 | 0.231 3 | 0.28 | 0.933 0 | 0.819 2 | 0.919 2 | 1.99 | |
| DPC-CE | 0.228 7 | 0.101 9 | 0.181 5 | 0.899 5 | 0.720 6 | 0.889 8 | |||
| 算法 | Compound | Pathbased | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 1.000 0 | 1.000 0 | 1.000 0 | 10 | 0.912 5 | 0.929 2 | 0.910 1 | 26 | |
| DPCSA | 0.843 9 | 0.828 4 | 0.839 2 | 0.731 1 | 0.613 3 | 0.707 3 | |||
| FHC-LDP | 0.855 3 | 0.848 3 | 0.850 1 | 5 | 0.714 4 | 0.562 9 | 0.604 2 | 8 | |
| ICKDP | 0.897 6 | 0.843 4 | 0.841 6 | 5 | 0.511 8 | 0.386 0 | 0.449 1 | 5 | |
| DBSCAN-DPC | 0.909 8 | 0.855 3 | 0.877 2 | 12/0.040 | 0.772 8 | 0.775 2 | 0.770 5 | 13/0.028 | |
| PPC | 0.758 6 | 0.777 4 | 0.715 2 | 1 | 0.651 9 | 0.607 6 | 0.639 2 | 11 | |
| DPC | 0.737 3 | 0.546 1 | 0.696 8 | 0.76 | 0.618 5 | 0.563 4 | 0.600 1 | 0.11 | |
| DPC-CE | 0.681 9 | 0.461 0 | 0.636 6 | 0.555 1 | 0.459 8 | 0.473 0 | |||
| 算法 | Complex9 | DB | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 1.000 0 | 1.000 0 | 1.000 0 | 35 | 1.000 0 | 1.000 0 | 1.000 0 | 32 | |
| DPCSA | 0.711 9 | 0.422 1 | 0.682 1 | 0.453 4 | 0.109 6 | 0.413 1 | |||
| FHC-LDP | 1.000 0 | 1.000 0 | 1.000 0 | 15 | 1.000 0 | 1.000 0 | 1.000 0 | 18 | |
| ICKDP | 0.940 5 | 0.868 7 | 0.917 4 | 12 | 1.000 0 | 1.000 0 | 1.000 0 | 7 | |
| DBSCAN-DPC | 1.000 0 | 1.000 0 | 1.000 0 | 20/0.040 | 1.000 0 | 1.000 0 | 1.000 0 | 20/0.040 | |
| PPC | 0.729 7 | 0.544 2 | 0.708 5 | 22 | 0.612 7 | 0.429 0 | 0.556 1 | 14 | |
| DPC | 0.745 4 | 0.609 4 | 0.740 2 | 2.00 | 0.512 0 | 0.325 1 | 0.459 6 | 0.83 | |
| DPC-CE | 0.711 6 | 0.448 4 | 0.541 5 | 0.717 6 | 0.469 9 | 0.644 3 | |||
| 算法 | Complex8 | R15 | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 0.997 6 | 0.998 7 | 0.997 3 | 32 | 0.997 1 | 0.996 4 | 0.996 9 | 26 | |
| DPCSA | 0.758 7 | 0.531 1 | 0.742 4 | 0.989 3 | 0.985 7 | 0.988 5 | |||
| FHC-LDP | 0.950 1 | 0.927 4 | 0.939 6 | 8 | 0.994 2 | 0.992 8 | 0.993 8 | 37 | |
| ICKDP | 0.933 8 | 0.920 9 | 0.923 7 | 10 | 0.994 2 | 0.992 8 | 0.993 8 | 10 | |
| DBSCAN-DPC | 0.954 6 | 0.941 2 | 0.925 7 | 15/0.029 | 0.994 2 | 0.992 8 | 0.993 8 | 19/0.040 | |
| PPC | 0.734 8 | 0.588 7 | 0.704 7 | 48 | 0.994 2 | 0.992 8 | 0.993 8 | 23 | |
| DPC | 0.794 6 | 0.703 6 | 0.772 1 | 1.72 | 0.994 2 | 0.992 8 | 0.993 8 | 1.74 | |
| DPC-CE | 0.727 6 | 0.576 6 | 0.713 3 | 0.994 2 | 0.992 8 | 0.993 8 | |||
| 算法 | S1 | Disk6000n | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 0.989 3 | 0.989 3 | 0.989 2 | 51 | 1.000 0 | 1.000 0 | 1.000 0 | 43 | |
| DPCSA | 0.988 0 | 0.988 4 | 0.986 9 | 0.238 8 | 0.092 9 | 0.241 8 | |||
| FHC-LDP | 0.988 4 | 0.988 1 | 0.988 2 | 23 | 1.000 0 | 1.000 0 | 1.000 0 | 7 | |
| ICKDP | 0.988 4 | 0.988 1 | 0.988 2 | 11 | 0.260 0 | 0.132 5 | 0.263 4 | 22 | |
| DBSCAN-DPC | 0.988 0 | 0.988 4 | 0.986 9 | 20/0.040 | 0.931 6 | 0.969 4 | 0.931 6 | 19/0.025 | |
| PPC | 0.988 7 | 0.988 4 | 0.988 6 | 4 | 0.168 6 | 0.252 5 | 0.169 9 | 2 | |
| DPC | 0.989 6 | 0.989 7 | 0.989 5 | 1.58 | 0.227 3 | 0.312 9 | 0.229 0 | 0.50 | |
| DPC-CE | 0.988 4 | 0.988 1 | 0.988 2 | 0.123 9 | 0.041 0 | 0.124 7 | |||

图8
算法在D3cno123数据集上的聚类效果"


图9
算法在Jain数据集上的聚类效果"


图10
算法在Compound数据集上的聚类效果"


图11
算法在Pathbased数据集上的聚类效果"

表4
UCI数据集上的聚类结果"
| 算法 | Vote | Libras | |||||||
|---|---|---|---|---|---|---|---|---|---|
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 0.494 3 | 0.571 0 | 0.484 8 | 53 | 0.667 5 | 0.398 1 | 0.601 8 | 8 | |
| DPCSA | 0.486 7 | 0.536 8 | 0.476 6 | 0.559 5 | 0.279 9 | 0.424 3 | |||
| FHC-LDP | 0.449 9 | 0.536 8 | 0.417 5 | 14 | 0.630 0 | 0.337 7 | 0.556 1 | 8 | |
| ICKDP | 0.575 7 | 0.694 9 | 0.574 9 | 5 | 0.602 3 | 0.309 5 | 0.524 3 | 10 | |
| DBSCAN-DPC | 0.480 7 | 0.568 0 | 0.438 3 | 20/0.040 | 0.671 3 | 0.396 4 | 0.590 4 | 6/0.037 | |
| PPC | 0.448 7 | 0.550 0 | 0.441 8 | 32 | 0.662 7 | 0.407 9 | 0.602 4 | 5 | |
| DPC | 0.469 4 | 0.536 7 | 0.459 8 | 0.23 | 0.635 5 | 0.350 0 | 0.566 8 | 0.24 | |
| DPC-CE | 0.456 0 | 0.510 1 | 0.446 4 | 0.590 1 | 0.321 5 | 0.514 7 | |||
| 算法 | Wine | Sonar | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 0.841 7 | 0.853 7 | 0.835 7 | 15 | 0.096 8 | 0.129 3 | 0.093 5 | 13 | |
| DPCSA | 0.564 7 | 0.505 4 | 0.548 6 | 0.062 8 | 0.063 0 | 0.050 9 | |||
| FHC-LDP | 0.743 5 | 0.726 9 | 0.739 1 | 20 | 0.069 6 | 0.073 3 | 0.065 1 | 5 | |
| ICKDP | 0.743 5 | 0.726 9 | 0.739 1 | 8 | 0.096 8 | -0.002 3 | 0.051 2 | 8 | |
| DBSCAN-DPC | 0.623 3 | 0.497 6 | 0.462 1 | 6/0.036 | 0.096 3 | 0.075 0 | 0.062 7 | 13/0.036 | |
| PPC | 0.825 2 | 0.836 8 | 0.819 1 | 7 | 0.058 2 | 0.068 0 | 0.054 7 | 13 | |
| DPC | 0.710 4 | 0.672 4 | 0.706 5 | 1.99 | 0.066 2 | 0.084 4 | 0.062 8 | 0.08 | |
| DPC-CE | 0.591 1 | 0.536 2 | 0.584 1 | 0.038 0 | 0.019 0 | 0.031 0 | |||
| 算法 | Pima | Haberman | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 0.084 8 | 0.123 2 | 0.081 5 | 57 | 0.037 2 | 0.111 2 | 0.029 6 | 31 | |
| DPCSA | 0.005 2 | 0.014 3 | 0.001 7 | 0.001 6 | -0.010 5 | -0.001 0 | |||
| FHC-LDP | 0.005 2 | 0.014 3 | 0.001 7 | 21 | 0.022 0 | 0.045 2 | 0.008 3 | 33 | |
| ICKDP | 0.005 2 | 0.014 3 | 0.001 7 | 11 | 0.000 3 | -0.000 4 | -0.002 1 | 9 | |
| DBSCAN-DPC | 0.032 7 | 0.086 7 | 0.022 8 | 12/0.030 | 0.033 5 | 0.029 3 | 0.019 9 | 7/0.0340 | |
| PPC | 0.052 4 | 0.096 1 | 0.051 0 | 5 | 0.011 8 | 0.036 2 | 0.008 6 | 16 | |
| DPC | 0.010 4 | 0.034 1 | 0.006 7 | 0.18 | 0.004 6 | 0.032 0 | 0.001 4 | 0.5 | |
| DPC-CE | 0.031 8 | 0.067 7 | 0.023 2 | 0.002 0 | 0.015 8 | -0.001 7 | |||
| 算法 | DNA | Heart | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 0.117 5 | 0.092 7 | 0.117 5 | 56 | 0.235 0 | 0.308 8 | 0.232 9 | 55 | |
| DPCSA | 0.051 8 | 0.028 4 | 0.051 8 | 0.123 5 | 0.098 1 | 0.097 4 | |||
| FHC-LDP | 0.050 0 | 0.040 1 | 0.050 0 | 32 | 0.175 4 | 0.207 4 | 0.163 1 | 15 | |
| ICKDP | 0.023 6 | 0.014 2 | 0.023 6 | 15 | 0.125 9 | 0.120 8 | 0.106 2 | 9 | |
| DBSCAN-DPC | 0.088 9 | 0.065 0 | 0.088 9 | 4/0.0280 | 0.144 6 | 0.149 3 | 0.102 9 | 7/0.040 | |
| PPC | 0.035 9 | 0.053 5 | 0.033 1 | 1 | 0.192 0 | 0.245 7 | 0.184 9 | 6 | |
| DPC | 0.047 1 | 0.077 7 | 0.043 3 | 0.06 | 0.134 6 | 0.178 4 | 0.129 4 | 0.17 | |
| DPC-CE | 0.009 5 | 0.028 9 | 0.009 5 | 0.154 2 | 0.172 3 | 0.139 4 | |||
| 算法 | Seeds | Thyroid | |||||||
| NMI | ARI | AMI | Arg- | NMI | ARI | AMI | Arg- | ||
| CBDPC | 0.788 9 | 0.814 2 | 0.784 8 | 15 | 0.711 4 | 0.798 9 | 0.684 9 | 59 | |
| DPCSA | 0.715 1 | 0.723 6 | 0.706 4 | 0.351 7 | 0.318 5 | 0.231 4 | |||
| FHC-LDP | 0.728 6 | 0.763 5 | 0.725 6 | 24 | 0.394 0 | 0.370 1 | 0.363 3 | 4 | |
| ICKDP | 0.741 0 | 0.788 0 | 0.738 1 | 10 | 0.431 3 | 0.424 0 | 0.319 4 | 9 | |
| DBSCAN-DPC | 0.725 1 | 0.739 8 | 0.718 5 | 11/0.040 | 0.415 5 | 0.509 3 | 0.369 5 | 6/0.025 | |
| PPC | 0.732 0 | 0.766 0 | 0.727 0 | 16 | 0.506 2 | 0.574 9 | 0.443 1 | 4 | |
| DPC | 0.742 4 | 0.745 5 | 0.736 6 | 0.06 | 0.270 8 | 0.165 3 | 0.246 1 | 1.30 | |
| DPC-CE | 0.698 9 | 0.741 6 | 0.695 2 | 0.173 6 | 0.157 4 | 0.151 8 | |||
表5
算法秩均值"
| 秩均值 | NMI | ARI | AMI |
|---|---|---|---|
| CBDPC | 1.403 8 | 1.384 6 | 1.384 6 |
| DPCSA | 6.038 5 | 6.384 6 | 6.038 5 |
| FHC-LDP | 3.807 7 | 3.826 9 | 3.692 3 |
| ICKDP | 4.519 2 | 5.000 0 | 4.692 3 |
| DBSCAN-DPC | 3.673 1 | 3.846 2 | 4.173 1 |
| PPC | 4.615 4 | 4.000 0 | 4.346 2 |
| DPC | 5.192 3 | 4.961 5 | 5.076 9 |
| DPC-CE | 6.570 0 | 6.596 2 | 6.596 2 |

图12
CBDPC算法统计检验"


图13
CBDPC算法参数分析"


图14
不同α1取值下CBDPC算法的聚类性能"


图15
不同α2取值下CBDPC算法的聚类性能"

表6
算法在所有数据集上的运行时间 单位:s"
| 数据集 | 运行时间 | |||||||
|---|---|---|---|---|---|---|---|---|
| CBDPC | DPCSA | FHC-LDP | ICKDP | DBSCAN-DPC | PPC | DPC | DPC-CE | |
| 2d4c2 | 0.264 | 1.826 | 0.021 | 0.325 | 0.202 | 0.221 | 0.091 | 18.219 |
| Ls | 0.745 | 4.448 | 0.817 | 0.180 | 0.339 | 0.244 | 1.168 | 214.018 |
| Donut2 | 0.297 | 2.512 | 0.305 | 0.703 | 0.220 | 0.194 | 0.790 | 25.373 |
| Complex9 | 2.150 | 7.712 | 0.918 | 3.139 | 1.680 | 1.313 | 1.328 | 3.378×10³ |
| DB | 0.226 | 1.958 | 0.004 | 0.150 | 0.090 | 0.172 | 0.064 | 4.422 |
| R15 | 0.196 | 2.378 | 0.051 | 0.230 | 0.104 | 0.210 | 0.075 | 1.814 |
| D13 | 0.162 | 2.854 | 0.056 | 0.169 | 0.083 | 0.210 | 0.074 | 2.293 |
| Xclara | 2.224 | 5.94 | 0.159 | 3.103 | 0.562 | 0.277 | 1.414 | 5.950 |
| DS850 | 0.250 | 1.785 | 0.007 | 0.135 | 0.134 | 0.215 | 0.088 | 13.736 |
| D3cno123 | 0.211 | 1.164 | 0.016 | 0.155 | 0.112 | 0.192 | 0.076 | 8.170 |
| Compound | 0.117 | 1.512 | 0.015 | 0.084 | 0.053 | 0.275 | 0.074 | 0.949 |
| Pathbased | 0.100 | 0.828 | 0.031 | 0.065 | 0.075 | 0.196 | 0.092 | 0.572 |
| Complex8 | 1.542 | 4.772 | 0.125 | 1.559 | 0.423 | 0.253 | 0.591 | 896.608 |
| Jain | 0.107 | 1.163 | 0.002 | 0.075 | 0.073 | 0.180 | 0.054 | 0.777 |
| S1 | 5.130 | 5.041 | 0.352 | 4.856 | 4.642 | 0.542 | 1.276 | 1.034×10⁴ |
| Disk6000n | 8.918 | 6.141 | 0.555 | 3.373 | 4.883 | 1.106 | 2.025 | 2.752×10⁴ |
| Libras | 0.142 | 0.954 | 0.005 | 0.079 | 0.081 | 0.222 | 0.065 | 0.167 |
| Wine | 0.093 | 0.568 | 0.002 | 0.036 | 0.078 | 0.188 | 0.046 | 0.143 |
| Sonar | 0.132 | 0.846 | 0.003 | 0.038 | 0.089 | 0.179 | 0.053 | 0.130 |
| Pima | 0.210 | 0.899 | 0.014 | 0.002 | 0.216 | 0.199 | 0.059 | 1.784 |
| Haberman | 0.097 | 0.793 | 0.002 | 0.047 | 0.076 | 0.187 | 0.050 | 0.383 |
| DNA | 2.140 | 6.006 | 0.115 | 2.587 | 0.744 | 0.234 | 0.240 | 2.385 |
| Heart | 0.384 | 1.251 | 0.002 | 0.106 | 0.079 | 0.198 | 0.069 | 0.156 |
| Seeds | 0.095 | 1.605 | 0.002 | 0.037 | 0.068 | 0.214 | 0.044 | 0.232 |
| Thyroid | 0.103 | 1.344 | 0.002 | 0.033 | 0.095 | 0.171 | 0.043 | 0.285 |
| Vote | 0.450 | 0.993 | 0.007 | 0.056 | 0.104 | 0.195 | 0.043 | 0.152 |
| 平均时间 | 1.019 | 2.588 | 0.138 | 0.820 | 0.589 | 0.300 | 0.384 | 1 631.989 |
| [1] | 周志华. 机器学习[M]. 北京: 清华大学出版社, 2016: 121-144. |
| [2] |
LU J Z, LIU J J, HAN X X, et al. Calibration Method of Particulate Matter Sensor Based on Density Peaks Clustering Combined with Stacking Algorithm[J]. Atmospheric Environment, 2024, 326: 120460.
doi: 10.1016/j.atmosenv.2024.120460 |
| [3] |
ZHANG Z L, YIN X L, HU W, et al. Machine Learning k-Means Clustering of Interpolative Separable Density Fitting Algorithm for Accurate and Efficient Cubic -Scaling Exact Exchange Plus Random Phase Approximation within Plane Waves[J]. Journal of Chemical Theory and Computation, 2024, 20(5): 1944-1964.
doi: 10.1021/acs.jctc.3c01157 |
| [4] |
BIAN J H, DAI C L, LI G H. Adaptive Channel-Weight Dual-Constrained Semi-Supervised EEG Clustering[J]. Biomedical Signal Processing and Control, 2024, 98: 106720.
doi: 10.1016/j.bspc.2024.106720 |
| [5] | TRON R, ZHOU X W, ESTEVES C, et al. Fast Multi-Image Matching via Density-Based Clustering[C]// 2017 IEEE International Conference on Computer Vision (ICCV). Piscataway: IEEE, 2017: 4077-4086. |
| [6] | KHILKHAL R, ISMAEL M. Brain Tumor Segmentation Utilizing Thresholding and k-Means Clustering[C]// 2022 Muthanna International Conference on Engineering Science and Technology (MICEST), Piscataway, IEEE: 2022: 43-48. |
| [7] | RODRIGUEZ A, LAIO A. Clustering by Fast Search and Find of Density Peaks[J]. Science, 2014, 344(6191): 492-1496. |
| [8] |
WANG Y Z, QIAN J X, HASSAN M, et al. Density Peak Clustering Algorithms: A Review on the Decade 2014-2023[J]. Expert Systems with Applications, 2024, 238: 121860.
doi: 10.1016/j.eswa.2023.121860 |
| [9] | 张强, 周水生, 张颖. 自适应密度峰值聚类算法[J]. 西安电子科技大学学报, 2024, 51(2): 170-181. |
| ZHANG Qiang, ZHOU Shuisheng, ZHANG Ying. Adaptive Density Peak Clustering Algorithm[J]. Journal of Xidian University, 2024, 51(2): 170-181. | |
| [10] |
WEI X X, PENG M S, HUANG H J, et al. An Overview on Density Peaks Clustering[J]. Neurocomputing, 2023, 554: 126633.
doi: 10.1016/j.neucom.2023.126633 |
| [11] |
DING S F, DU W, LI C, et al. Density Peaks Clustering Algorithm Based on Improved Similarity and Allocation Strategy[J]. International Journal of Machine Learning and Cybernetics, 2023, 14(4): 1527-1542.
doi: 10.1007/s13042-022-01711-7 |
| [12] |
YU D H, LIU G J, GUO M Z, et al. Density Peaks Clustering Based on Weighted Local Density Sequence and Nearest Neighbor Assignment[J]. IEEE Access, 2019, 7: 34301-34317.
doi: 10.1109/Access.6287639 |
| [13] |
LI T, LI B Y, XIN X W, et al. A Novel Tree Structure-Based Multi-Prototype Clustering Algorithm[J]. Journal of King Saud University - Computer and Information Sciences, 2024, 36(3): 102002.
doi: 10.1016/j.jksuci.2024.102002 |
| [14] |
ZANG W K, LIU X C, MA L L, et al. Density Peaks Clustering Based on Superior Nodes and Fuzzy Correlation[J]. Information Sciences, 2024, 672: 120685.
doi: 10.1016/j.ins.2024.120685 |
| [15] |
HASSAN M, NAJMEH M. AnEfficient Clustering Algorithm Based on Searching Popularity Peaks[J]. Pattern Analysis and Applications, 2024, 27(2): 67.
doi: 10.1007/s10044-024-01261-4 |
| [16] |
GUO W J, WANG W H, ZHAO S P, et al. Density Peak Clustering with Connectivity Estimation[J]. Knowledge-Based Systems, 2022, 243: 108501.
doi: 10.1016/j.knosys.2022.108501 |
| [17] | GUAN J Y, LI S, HE X X, et al. Fast Hierarchical Clustering of Local Density Peaks via An Association Degree Transfer Method[J]. Neurocomputing, 2021, 445: 401-418. |
| [18] |
HOU J, LIN H S, YUAN H Q, et al. Flexible Density Peak Clustering for Real-World Data[J]. Pattern Recognition, 2024, 156: 110772.
doi: 10.1016/j.patcog.2024.110772 |
| [19] |
GUO W J, CHEN W, LIU X G. Density Peak Clustering by Local Centers and Improved Connectivity Kernel[J]. Information Sciences, 2024, 666: 120439.
doi: 10.1016/j.ins.2024.120439 |
| [20] | MILAAN P. Clustering Datasets (2022)[EB/OL]. [2024-5-11]. https://github.com/milaan9/ClusteringDatasets. |
| [21] | BLAKE C L, MERZ C J. UCI Repository of Machine Database (2023)[EB/OL]. [2024-6-15]. https://archive.ics.uci.edu/datasets. |
| [22] | VINH N, EPPS J, BAILEY J. Information Theoretic Measures for Clustering Comparison: Variants, Properties, Normalization and Correction for Chance[J]. Journal of Machine Learning Research, 2010, 11: 2837-2854. |
| [23] |
DONALD W Z, BRUNO D Z. Relative Power of the Wilcoxon Test, the Friedman Test, and Repeated- Measures ANOVA on Ranks[J]. The Journal of Experimental Education, 1993, 62(1):75-86.
doi: 10.1080/00220973.1993.9943832 |
| [1] | 孙玉雯, 谢荣, 王叶斐, 许述文, 刘峥. 基于ST-GCN的多功能雷达工作模式识别方法[J]. 西安电子科技大学学报, 2025, 52(5): 121-132. |
| [2] | 李文刚, 王乾雄, 黄郡, 慈国辉, 翟肖童. 一种非合作多目标的分布式定位算法[J]. 西安电子科技大学学报, 2024, 51(6): 1-9. |
| [3] | 张强, 周水生, 张颖. 自适应密度峰值聚类算法[J]. 西安电子科技大学学报, 2024, 51(2): 170-181. |
| [4] | 丁昕苗, 王家兴, 郭文. 三维注意力增强的暴力场景检测算法[J]. 西安电子科技大学学报, 2024, 51(1): 114-124. |
| [5] | 赵浩钦, 杨政, 司江勃, 石嘉, 严少虎, 段国栋. 一种聚类辅助的智能频谱分配技术研究[J]. 西安电子科技大学学报, 2023, 50(6): 1-12. |
| [6] | 刘高高, 黄东杰, 席昕, 李昊, 曹旭源. 一种特征融合的工作模式识别方法[J]. 西安电子科技大学学报, 2023, 50(6): 13-20. |
| [7] | 熊敬伟, 潘继飞, 毕大平, 杜明洋. 面向雷达行为识别的多尺度卷积注意力网络[J]. 西安电子科技大学学报, 2023, 50(6): 62-74. |
| [8] | 王潮, 周梦, 丁寅凡, 汤霖. 视觉拐弯:转角视野盲区无线感知监测算法[J]. 西安电子科技大学学报, 2023, 50(2): 197-204. |
| [9] | 杨秋,顾杰,魏平. 利用幅度重排的机载火控雷达工作模式识别方法[J]. 西安电子科技大学学报, 2021, 48(2): 42-48. |
| [10] | 闫林,刘凯,段玫妤. 一种用于点云分类的轻量级深度神经网络[J]. 西安电子科技大学学报, 2020, 47(2): 46-53. |
| [11] | 杨利英;杨胜楠;袁细国;耿芳歌;张军英. 泛癌症DNA甲基化位点聚类分析[J]. 西安电子科技大学学报, 2018, 45(4): 23-28. |
| [12] | 杨利英;殷黎洋;袁细国;张军英. 富集分析框架下的致病SNP位点识别[J]. 西安电子科技大学学报, 2016, 43(3): 43-48. |
| [13] | 卢红喜;李东霖;刘宏伟;索志勇;宋文青;保铮. 双基线极化干涉SAR植被参数反演[J]. J4, 2015, 42(6): 23-29. |
| [14] | 刘家辰;苗启广;宋建锋;曹莹 . 使用聚类稳定性分析方法增强单类学习算法 [J]. J4, 2015, 42(2): 58-64+121. |
| [15] | 刘杰;王宇平. 一种采用聚类单纯形搜索的引力算法[J]. J4, 2014, 41(6): 100-105. |
|
||
